esc

↑↓ navigate↵ open

Software

Open-source implementations of the research

Each package implements one of the ideas on the research page and works with optimization models as they are already written in JuMP, so that learning, sensitivity analysis, and models of uncertainty can be applied without rebuilding a model for each method. They are grouped by the idea they implement; within each group, general tools come first and their applications follow. Each package has a page on the design ideas it contributes, with an example and the research it supports.

Learning solution maps

Data, training, and supervision for solution maps

Infrastructure for learning approximations of parametric optimization problems: Generating reference solutions and sensitivities from existing models, training proxies on them, and solving batches of problems on GPUs. See Learning Solution Maps and Continuation-Value Representations.

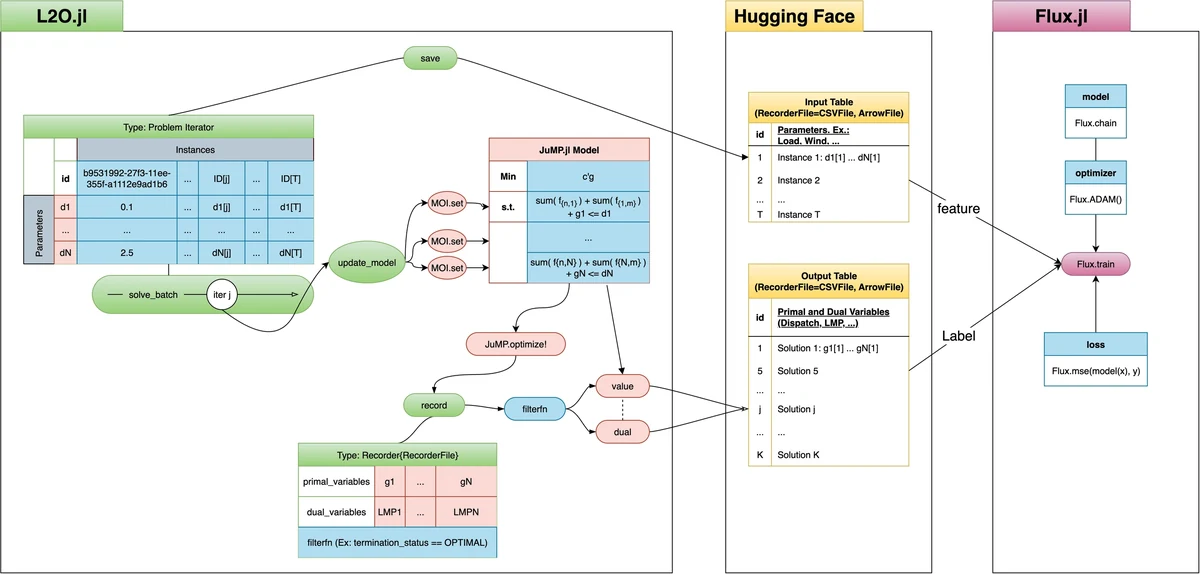
LearningToOptimize.jl pipeline in three panels. In the package panel, a ProblemIterator holds a table of instances, one parameter vector per identifier; solve_batch loops over them, update_model sets each parameter of the JuMP model with MOI.set, and JuMP.optimize! solves it; a Recorder then stores the primal and dual variables that pass its filter. The parameters and the recorded solutions are saved as input and output tables, published on Hugging Face, which Flux.jl reads as features and labels in Flux.train with a model, an optimizer and a loss.
LearningToOptimize.jl: generate data from a parametric JuMP model, store it, train a proxy.
Masked Sobolev training: dataset solves with DiffOpt provide decisions and sensitivities; the proxy matches both through automatic differentiation.
Masked Sobolev training: dataset solves supply reference decisions and selected sensitivities; the proxy matches both.

Organization lead · solution-map learning

An open-source organization for learning optimization proxies, hosting with collaborators:

Policies for multistage decisions

State policies implemented by optimization, and the models that test them

Training policies whose state targets are implemented by an optimization over the operational model, and the multistage planning models in which those policies are compared with stochastic dual dynamic programming. See Policies for Multistage Decisions and Planning and Realization Mismatch.

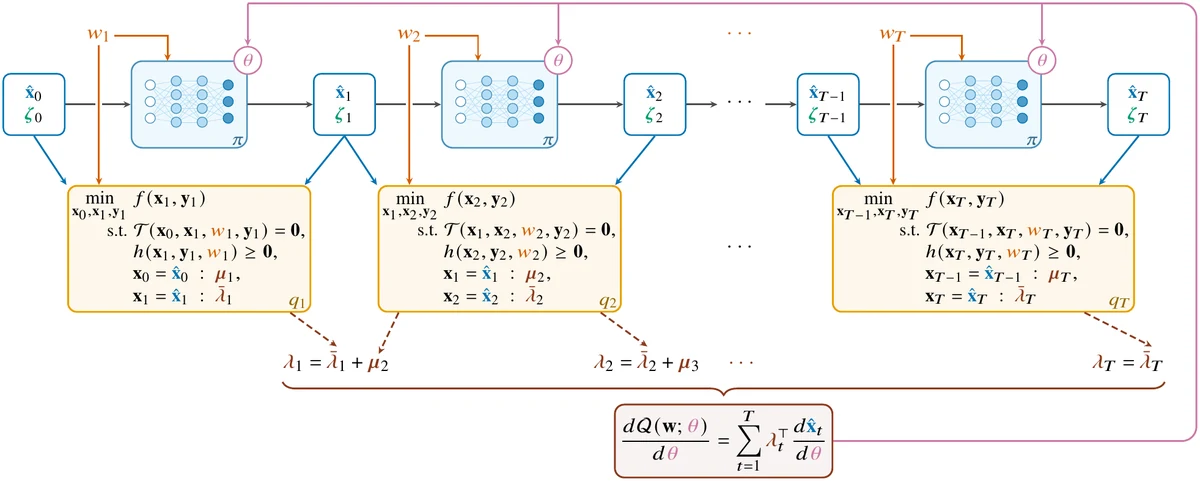
Training a state-consistent decision rule: a recurrent policy with shared weights emits targets stage by stage; independent stage problems, solved in parallel, return the multipliers that form the gradient.

Author · policy learning

Trains two-stage generalized decision rules: A parametric policy prescribes state targets, an optimization implements them, and the multipliers of the target constraints supply the gradient. Examples cover hydro dispatch and inventory control; DecisionRulesExa.jl solves the stage problems on GPUs.

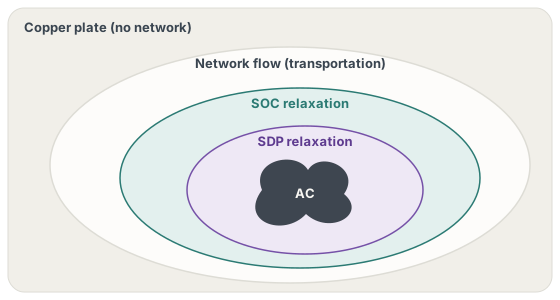
Nested relaxations of the AC power-flow feasible set: SDP inside SOC inside network flow inside copper plate.

Author · multistage hydrothermal planning

Multistage hydrothermal dispatch solved with SDDP over any PowerModels network formulation, from transportation models to convex relaxations of AC power flow; used to measure the cost of planning on a simplified network and as an SDDP baseline for decision rules.

Uncertainty and ambiguity · Multi-level decision problems

Uncertainty, market response, and solution sensitivity

A general engine for decisions under estimated uncertainty, its specialization to offers that are evaluated through market clearing, and the sensitivity layer that lets parameters of either be tuned through the decisions they produce. See Uncertainty and Ambiguity, Endogenous Response, and Differentiating Optimization Models.

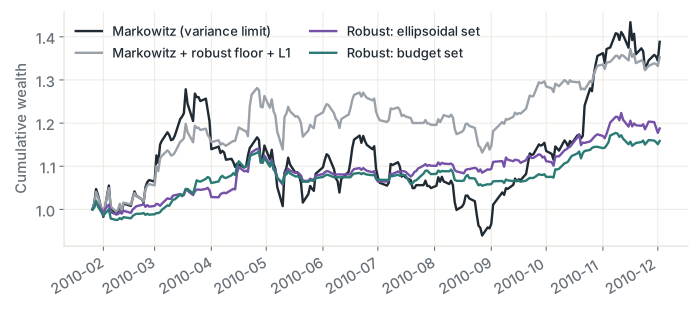
Cumulative wealth during a rolling backtest for nominal and robust allocation strategies.

Author · uncertainty, ambiguity, and risk

Composes forecasts, uncertainty and ambiguity sets, risk measures, and constraints into nominal, robust, and distributionally robust allocation models, each compiled to a tractable reformulation, and compares them in rolling backtests.

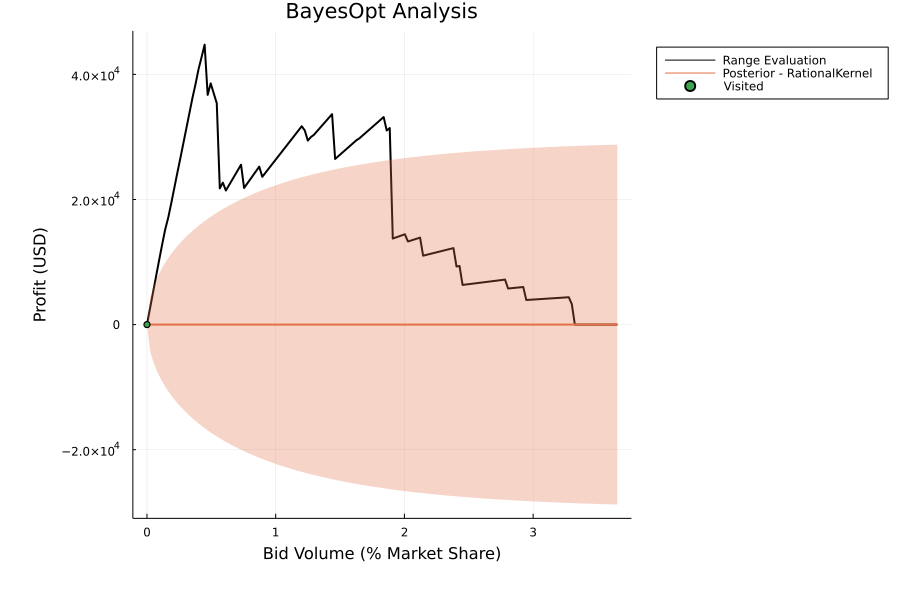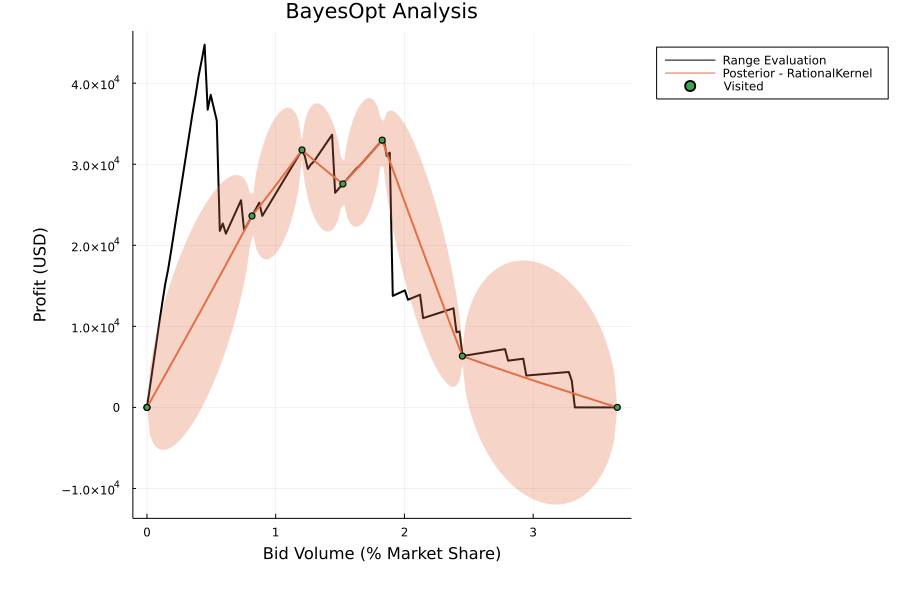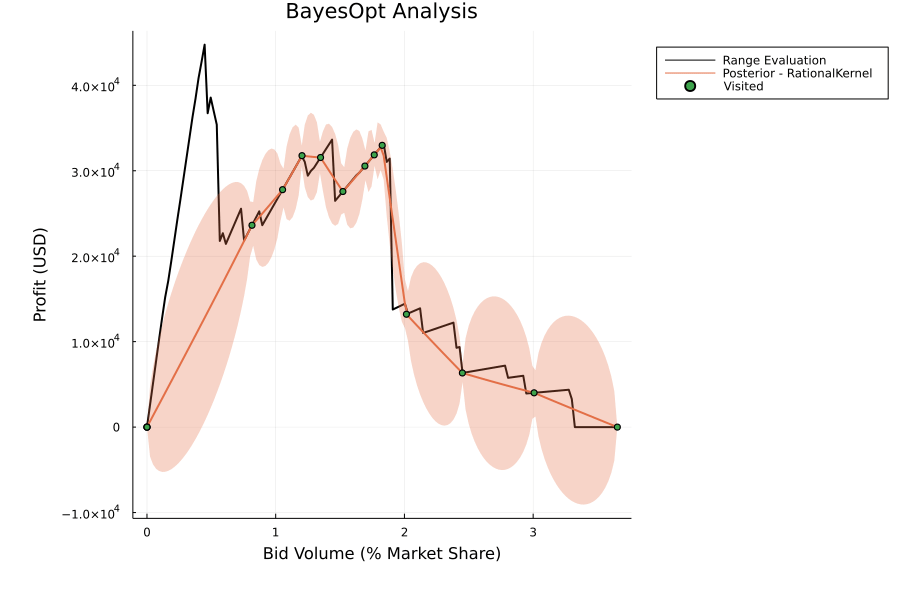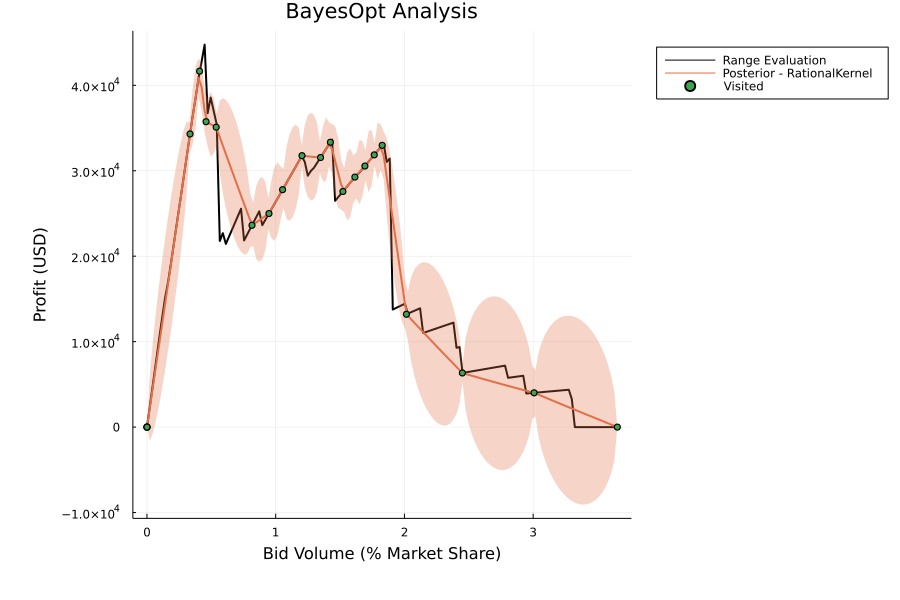
Bayesian optimization fitting a Gaussian-process surrogate to a jagged profit curve.

Author · market offers

Turns a market-clearing model into an evaluation of offers—build the market, change bids, clear, compute profit—so that gradient-based and derivative-free methods search over the same decision process.

Learned mapoffers, targets, or model coefficientsOptimization with its own objectivemarket clearing, simplified model, or controllerEvaluationthe decision maker’s criterion Learned mapoffers, targets, or model coefficientsOptimization with its own objectivemarket clearing, simplified model,or controllerEvaluationthe decision maker’s criterion

Contributor · solution sensitivities

Part of the JuMP ecosystem: Solution and objective sensitivities of optimization models with respect to named parameters, independent of the solver. Contributions: The module for smooth nonconvex programs at regular local solutions, objective sensitivities, and, with Joaquim Dias Garcia, the parameter-centric interface.

Also: SquidGame.jl, strategy tournaments for repeated games such as the iterated prisoner’s dilemma, written for fun. More on GitHub.